Engineering journal

LoraDB Blog

Engineering notes, architecture pieces, release notes, and design writing from the LoraDB team.

LoraDB v0.17: inside lora-graphql

· 10 min read
The LoraDB team
Engineering

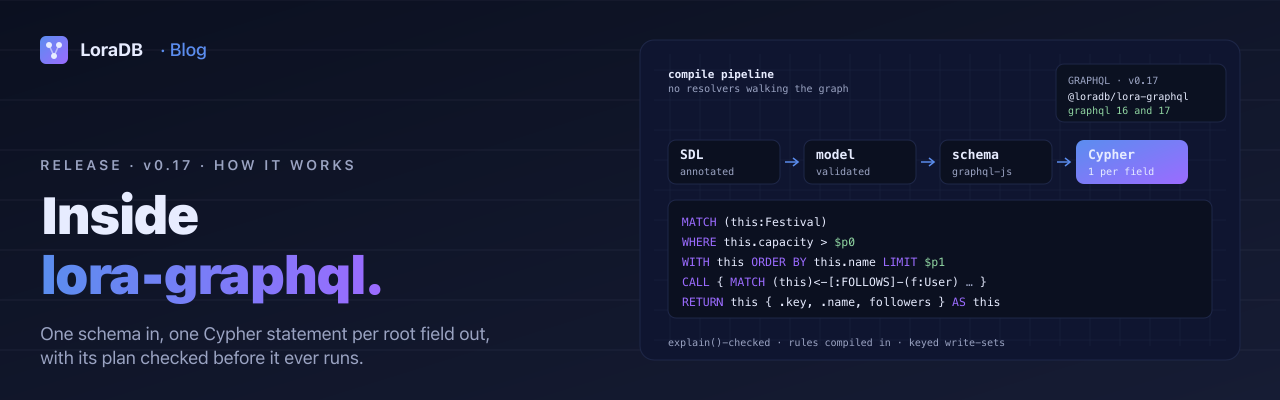
LoraDB v0.17. Inside lora-graphql.

v0.16 introduced @loradb/lora-graphql. This post is about how it works: what happens between an annotated schema and the Cypher that reaches the engine, and why it is built that way.

The short version: there are no resolvers that walk the graph. A GraphQL operation is compiled, root field by root field, into one parameterised Cypher statement whose plan can be checked before it ever runs.
LoraDB v0.16: GraphQL, and an engine that finds the seek

· 5 min read
The LoraDB team
Engineering

LoraDB v0.16 adds a GraphQL API, and a planner that no longer needs help finding an index.

The headline is a new package, @loradb/lora-graphql. One annotated schema becomes an executable GraphQL API whose operations compile to parameterised Cypher. Building it put the engine under a kind of load the Cypher examples never did, and most of this release's engine work came out of that: condition pushdown, IN seeks, early LIMIT inside transactions, temporal range indexes, writes in CALL { }, and a committed change feed.

LoraDB v0.15: benchmarks in public

· 6 min read
The LoraDB team
Engineering

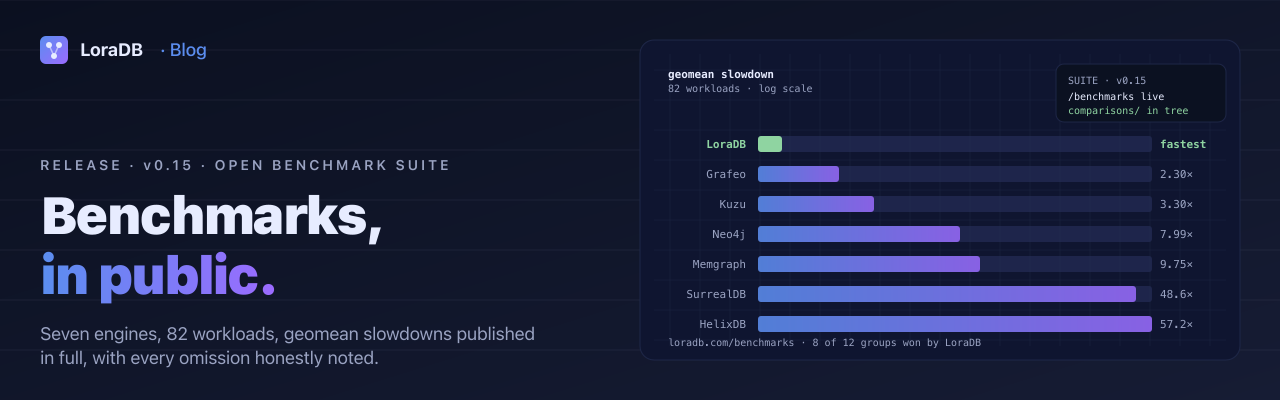
LoraDB v0.15. Benchmarks, in public.

LoraDB v0.15 publishes the numbers.

For most of the release journey the only benchmarks people saw were our internal smoke gates: a fixed set of workloads, a baseline, and "don't regress." That's enough to keep the engine honest with itself. It says nothing about how LoraDB compares to the other embedded and server graph engines a reader might already be using.

v0.15 closes that gap. The comparisons/ crate that drives the head-to-head suite is now in tree. The full report is committed at comparisons/report.md. A new /benchmarks page renders that report with per-engine ranking, per-group breakdowns, and a head-to-head page per competitor. Every workload that was skipped on a given engine carries the reason next to it.

LoraDB v0.14: hot paths and honest errors

· 10 min read
The LoraDB team
Engineering

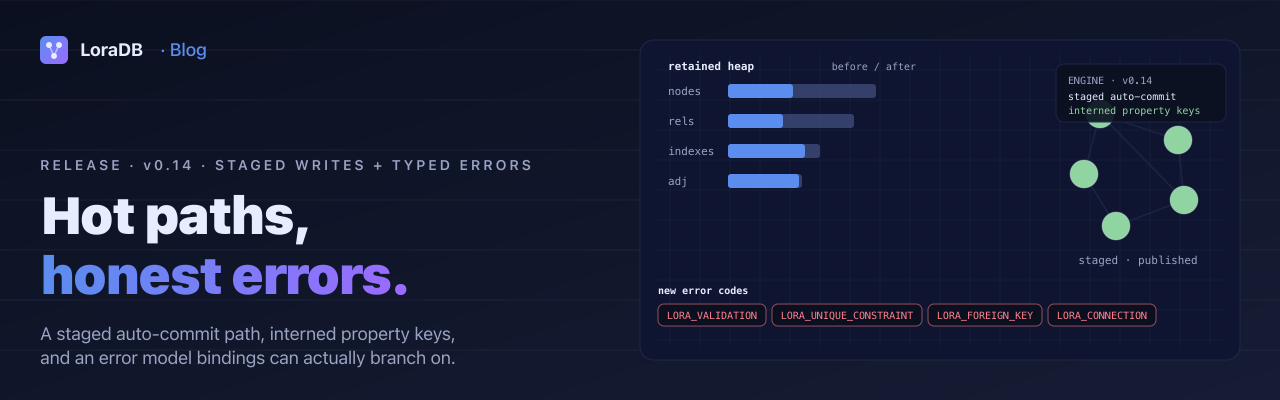
LoraDB v0.14. Hot paths, honest errors.

LoraDB v0.14 is a hardening release.

v0.11 put the engine behind a URL. v0.12 turned vectors into real indexes. v0.13 made data round-trip. v0.14 goes back to the engine and tightens three things that previous releases let slide: the write path, retained memory on large imports, and what an error actually says when something fails.

LoraDB v0.13: Rows in, graph out

· 8 min read
The LoraDB team
Engineering

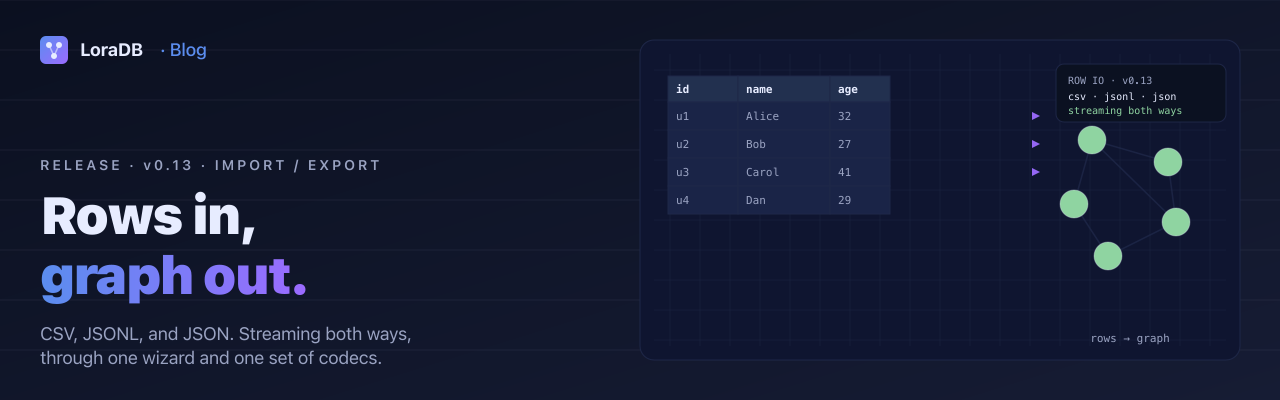
LoraDB v0.13. Rows in, graph out.

LoraDB v0.13 is an import / export release.

v0.5 made the engine stream. v0.6 made persistence feel like a system. v0.7 was a process release. v0.8 made plans and runtime metrics easier to inspect. v0.9 gave the planner a schema catalog. v0.10 made the function library a library. v0.11 put the engine behind a URL at play.loradb.com. v0.12 turned vectors into real indexes.

v0.13 turns the playground from a write-only sandbox into something you can put real data into. There is a new crate for row-level codecs, a bulk import / export driver in lora-database, three formats sharing one lossless value model, and a wizard that walks the whole pipeline from "drop a file" to "rows in the graph."

LoraDB v0.12: Vectors, end to end

· 8 min read
The LoraDB team
Engineering

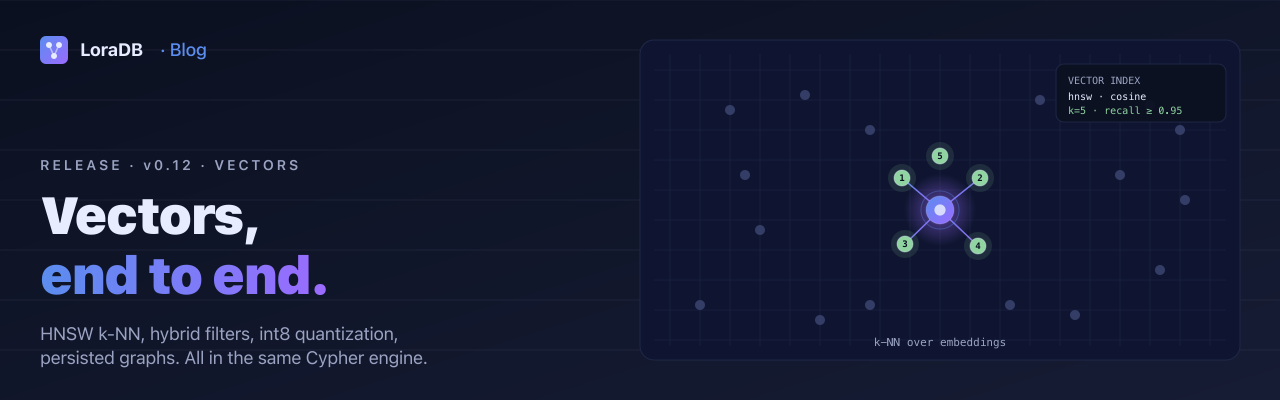
LoraDB v0.12. Vectors, end to end.

LoraDB v0.12 is a vector release.

v0.5 made the engine stream. v0.6 made persistence feel like a system. v0.7 was a process release. v0.8 made plans and runtime metrics easier to inspect. v0.9 gave the planner a schema catalog. v0.10 made the function library a library. v0.11 put the engine behind a URL at play.loradb.com.

v0.12 turns the vector type into a real index. Until this release a VECTOR value was a first-class property you could store, score, and return, but CREATE VECTOR INDEX was a catalog entry with no backing structure. Every k-NN query did a flat scan over every label-matching node. v0.12 keeps that behaviour as a deliberate fallback and adds an HNSW backend, hybrid pre-filters, four similarity metrics, int8 quantization, async populate, and snapshot persistence behind it. The playground gets a tuning wizard so none of this requires reading the catalog by hand.

Where SQL quietly degrades

· 11 min read
Joost van Berkel
Author, LoraDB

I do not want to write a post about how SQL is bad. SQL is not bad. Postgres is one of the most well-engineered pieces of software on the planet, and the relational model has held up for fifty years for very good reasons.

But the workloads I see developers actually building today are not the workloads SQL was tuned for. And in almost every one of those workloads, relational performance degrades. Not because of one catastrophic failure, but because of a stack of small frictions that compound into something you eventually start working around with caches, read replicas, materialized views, and a Slack channel called #schema-discussion.

This post is about where that degradation happens, and why it is structural rather than fixable with another index.

LoraDB v0.11: Query playground in your browser

· 6 min read
The LoraDB team
Engineering

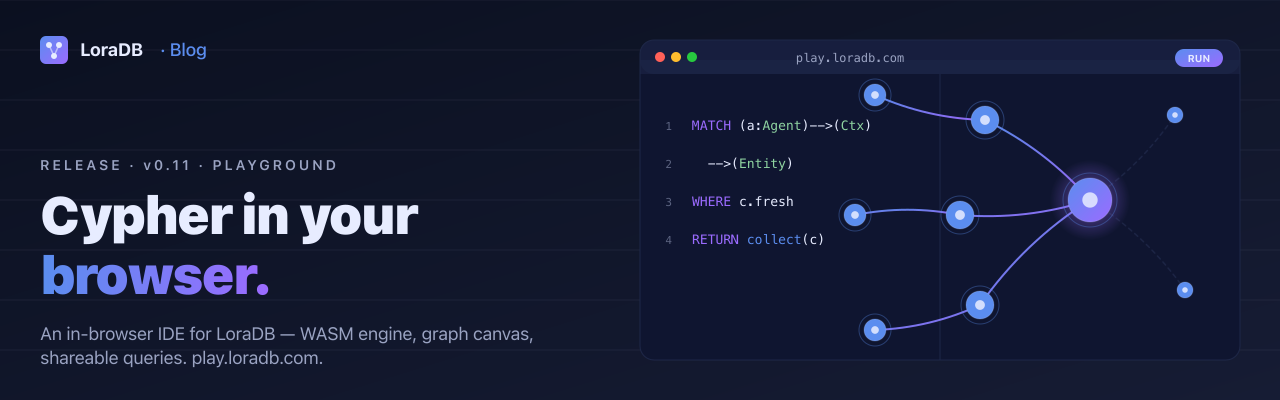
LoraDB v0.11 — query playground in your browser.

LoraDB v0.11 is a surface release.

v0.5 made the engine stream. v0.6 made persistence feel like a system. v0.7 was a process release. v0.8 made plans and runtime metrics easier to inspect from bindings. v0.9 gave the planner a schema catalog. v0.10 made the function library a library.

v0.11 puts the engine behind a URL. play.loradb.com is a browser playground for writing LoraDB queries, running them against an in-tab database, and seeing the results as a graph, table, or JSON. It ships as a static Next.js export and runs the database through WebAssembly in the browser.

LoraDB v0.10: one canonical name per concept

· 10 min read
The LoraDB team
Engineering

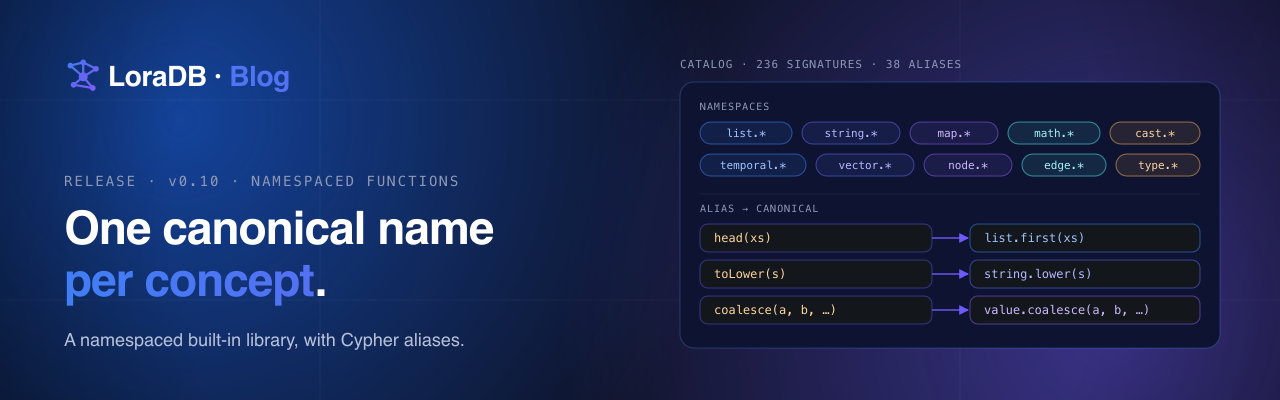
LoraDB v0.10 — one canonical name per concept.

LoraDB v0.10 is a function-surface release.

v0.5 made the engine stream. v0.6 made persistence feel like a system. v0.7 was a process release. v0.8 made the planner and executor observable. v0.9 gave the planner a real schema catalog.

v0.10 does the same thing for the function library: the engine now has one canonical name per concept, grouped into namespaces, with the analyzer, executor, optimizer, docs, and binding tests all reading from the same table.

LoraDB v0.9: indexes, constraints, and a real schema catalog

· 8 min read
The LoraDB team
Engineering

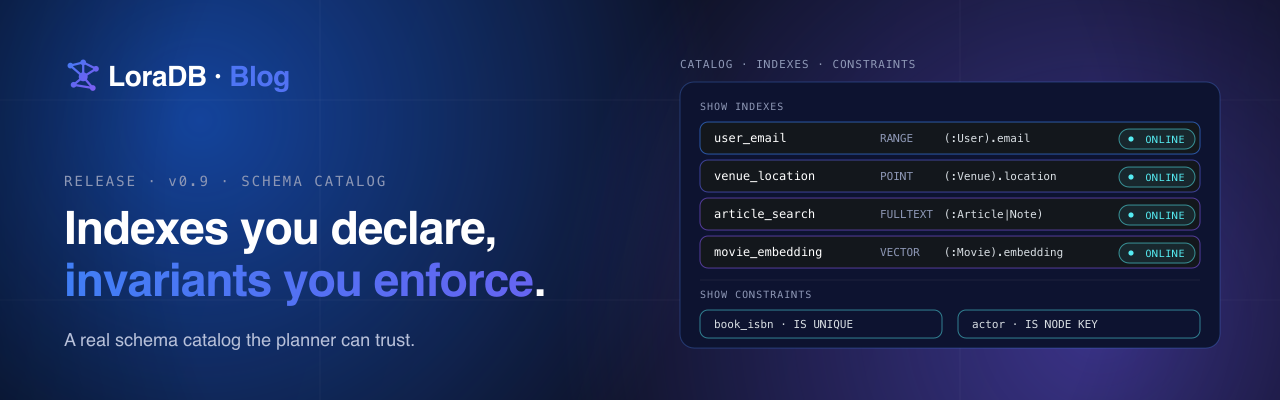
LoraDB v0.9 — indexes, constraints, and a real schema catalog.

LoraDB v0.9 is a schema-catalog release.

v0.5 made the engine stream. v0.6 made persistence feel like a system. v0.7 was a process release. v0.8 made the planner and executor observable. v0.9 closes the next gap: the planner now has a real schema catalog to plan against, and the engine has real constraints to enforce.

The result is a single coherent surface — index DDL, constraint DDL, catalog-backed scans, full-text and vector query procedures — wired through the parser, store, optimizer, executor, WAL, and snapshots.